
The Statistical Crisis in Science

The main points of view are from a lecture by Andrew Gelman, The State Crisis in Science, which is partly from Kamoun, S. (2022). Death by Statistics. Zenodo and some of his own thoughts.
The questions in this article can also be addressedStatistics on the application and application of statistics Learn.、Scientific theory and practical experienceHow the concept of a relatively close read together is developed in different contexts.
When we study statistical data, we want to “data speak”, and tell us what they represent. Data may really speak, but people cannot understand it directly, so statistics assume the role of translator.
Modern science uses statistics almost everywhere: analyses biochemical experiments, observations of clinical data, studies of election results... Data are everywhere, statistics are everywhere. Statisticians explore methods and share their findings with researchers in other areas.
Hypothesis testing It is likely that one of the most important innovations in statistics is the following: It deals with the most common problem in statistics, namely,How to measure uncertaintyI'm sorry. In nearly 100 years of statistical research, hypothetical testing has been one of the active areas. For many applied researchers, “convincing the results of the tests” seems to be a good idea and often leads to actionable decision-making.
The problem is that this also constitutes a type of statistical crisis in modern science: In reality,Tests for non-satisfactory preconditions、Multiple comparisonsandSelective reportingThis would allow the hypothetical test to give seemingly powerful but possibly absurd results; at times, people sometimes have more confidence in a number than in the field experience accumulated over the years.
The hypothesis is strong, but it depends on the premise.
Statistical inferences rely on a range of assumptions: for example, independent and distributed (i.i.d.) sampling, random sampling, controllability of noise structures, sound modelling, etc. The blogger says that the government is not a party to the law.Non-random sample (not random sample) There is also a high degree of data mix of noise, deviation and selection mechanisms.
Directly applying hypothetical tests on these data, the “not significant/not significant” conclusions obtained may be misleading. The hypothetical test can lead to a strong conclusion, but,Is it applicable in this study?Much depends on the researcher ' s knowledge of the field and the quality of the research design.
Even when using mature statistical tools, researchers may not be able to draw the right conclusions. No statistical method can completely avoid the wrong results or substitute for clear thinking if scientists follow the tools blindly and lack critical thinking. Statistics cannot complete the reasoning; to do so, it still requires an understanding of statistical tools and field knowledge.
p-value and p-racking
p-value indicates:When the zero is realHow likely is it to observe “extreme or more extreme than the current result”. It measures “how unusual this data is under zero”, not “conclusion is a real probability”.
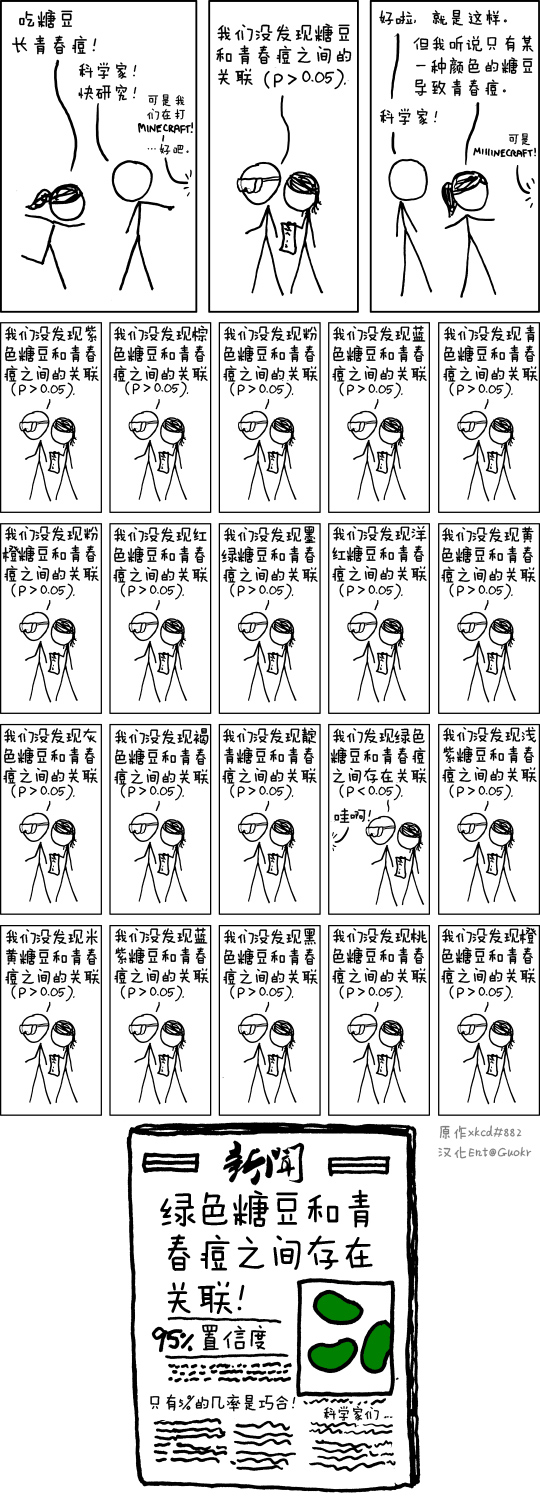
In an independent, well-designed test, p-value below 0.05 may be of further concern; but the chance is that if a large number of comparisons, models or indicators are started, some low p-values can also be generated. Even if there are no interesting real effects, as long as there is enough research, there are some “notable” results due to quantitative effects.
If the researchers do the following things, whether they want to or not, they're easily present. p-hacking(Repeatedly to explore analytical pathways for the release of “significant” results):
- Repeated attempts at different variables, different features, different grouping
- Continuous change of model, loss function, threshold, cessation rule
- Only the “most visible” set of results are reported, while unvisible attempts are ignored
Yes. Publish or Perish Under pressure, p-hacking is both tempting and common, but it systematically creates false conclusions and erodes the credibility of research. This phenomenon is not uncommon in empirical research, and writers and periodicals sometimes acquiesce in suspicious practices.
First-time scholars and non-statisticians also often confuse the assumption that when p-value is below the threshold, we reject the assumption. A natural but wrong idea:When p-value is greater than the threshold, the original assumption is accepted; however, this is equally wrong. Fisher interprets the higher P value (which represents no evidence of significantness) as stating that the data in this group cannot be judged sufficiently. We quote:
“Believe that a hypothesis has been proven to be true, simply because it does not contradict known facts, this logical misunderstanding is lacking in statistical inferences, and so is the case in other types of scientific reasoning. When the distinguishingness test is used accurately, the distinguishingness test can be rejected or rejected as long as it contradicts the data, but the distinguishingness test never confirms that the presumptions must be true, ...”
The hypothetical test is therefore aimed at finding evidence to reject the original hypothesis, not at proving what was correct. Where there is no sufficient evidence to reject the original assumption, the expression “accepts the original assumption” is usually used instead of “does not reject the original assumption”. The “no-rejection” does not give a clear conclusion: we did not say that the original assumption was correct or that it was incorrect. In short, the main purpose of the hypothetical test was to refuse rather than accept it.
With regard to the hypothetical test of statistical distribution, Yihui has previously written a blog that is very similar to the issues discussed here, and its core conclusions can be cited as follows:
The overall distribution of data tested seems to be of little use, and rejection of the zero assumption, i.e., the data are not subject to a distribution, tends to render the premise of the work to be done below unworkable — which would obviously be tragic; If the zero scenario is not rejected — which is almost useless, because not to reject it does not mean that other zero scenarios can be rejected — you still do not know what the distribution of data is — which is obviously even worse; So we're gonna cover our eyes, pretend we can't see, and like mathematical statisticians, we're assuming that X is in line with the Paretto distribution.
The #Yihui culture is really special.Original references
For p-haking, this is a figure that can be seen: the so-called remarkable gain from the luck of repeat experiments. The experimenter may not feel like he's in p-haking, but the behavior is pretty close. The figure is from the statistical capital, with the original source xkcd.
About visualization
Visualization is also an important part of statistics; in the papers it often carries a more direct communication function than the body of the text. A good chart allows readers to quickly grasp what the author wants to say, without relying on large text. However, the problem in the area of visualization is not less than the hypothetical test. Cleveland has discussed graphic deficiencies decades ago, and for nearly 10 years there have been a great deal of criticism of Barplot by academics, but the top journals still have a very poor quality Barplot. Researchers use them to mask shortcomings in experimental data and to deceive reviewers and editors to obtain publication opportunities.
An Express: Autovariate Selection in Economics
When you read the rest of this section, please keep thinking about this:Are we testing the theory of data or are we building it to accommodate our prejudices?
In machine learning (ML), automatic feature selection (e.g. LASSO, Stepwise, Random Forest integration) is popular because the target is to predict precision. As long as it is well performed on the test set, it is not important how the variables are selected.
In economics, however, the goal is usually a causal assumption. We need to see the coefficients of a given variable, like a policy shock.$\beta$The prominence. If we use the statistical software to bring back the step-by-step, or we manually try to combine the control variables, we remove those."Not significant"..the variables, keep those."Not significant"♪ And the variable that looks like ♪"Clean Model"But often it's already in the grey area of P-haking, even direct cheating. Edward Leamer, an article back in 1983, Let'This issue is discussed in the Con Out of Economics, but it is still widespread in all fields of empirical research decades later.
The standard P-value calculation hypothesis model is set before the data are viewed. If you choose first with data"Best"Variable, calculate the P value on the same data, and then the P value is completely invalid. The data freedom has been consumed to screen models, but no penalties have been imposed in the calculations. This leads to a serious underestimation of standards and a low P value. The extrapolation after the selection of variables is not valid in the economics scene.
Even if the researchers did not conduct P-haking subjectively and maliciously, there were numerous minor choices in the processing of the data (e.g., are the control variables added? are logarithms taken?). If these choices depend on “the availability of significant results”, the eventual statistical prominence is an illusion.
For ordinary researchers, it is more honest to do sensitivity analysis: show whether the conclusions are still robust under different control variables, rather than just the P. < 0.05 Results. But... Publish or Perish The pressure hangs on almost every researcher, and honesty may not always be rewarded.
More robust use advice
Distinguishing “exploration research” from “certification research”. For validation studies, the researchers have identified assumptions, model setting, variable definition and sample volume calculations before looking at the data; in this case, the P value is meaningful. The exploratory research is an attempt to find patterns when data are available, which is not problematic and even essential for scientific discovery.
Focus on the effect between confidence, rather than just reporting P values, and tell readers"How much is it?": 1% increase in income or 50% increase. More information is available on the estimates of confidence interval than on simple points. In particular, a scattered map should be used instead of a vague structure such as a bar chart, which would clearly show the location of each point before describing the overall distribution, rather than concealing precise data behind the blurry.
When conducting sensitivity analysis, do not simply show the smallest P-value model; try to change the combination of control variables, the way data are cleaned and the function form (linear vs logarithms). If the core conclusion is stable under 80% of modeling, the conclusion is robust; if the conclusion is based only on a few specific control variables, it is likely to be just noise. This has been described in recent literature as testing “effect vibrations”.
Concluding remarks
The statistical crisis facing modern science is discussed in this paper, based on the limitations of the hypothetical tests. The error of P-value, the proliferation of P-hattering, the visualization of misdirected, and the trap of “automatic variable selection” in empirical economics are often the underlying disregard for the application of the premise of statistical methods and the logic of scientific inferences.
Statistics help us to judge from data, but inappropriate use can also create false images. To reduce this risk, a distinction should be made between exploratory and certification studies, attention should be paid to the magnitude of the effects and confidence zones, and sensitivity analyses should be conducted to test the soundness of the conclusions. Statistical methods cannot replace clear thinking and field knowledge; in the face of uncertainty, data still need to be interpreted honestly and rigorously, rather than simply pursuing “significant” figures.
- Title: The Statistical Crisis in Science
- Author: Hyacehila
- Created at : 2026-01-24 02:00:00
- Link: https://hyacehila.github.io//blog/2026/01/24/the-statistical-crisis-in-science/
- License: This work is licensed under CC BY-NC-SA 4.0.