
Database Systems Concepts: Data Models, Transactions, and Query Processing

Introduction
Database management system ( DataBase-Management System, DBMS) It consists of a collection of interrelated data and a set of procedures for accessing them. This data set is commonly referred to as a database (database) and contains information on an enterprise. The main objective of DBMS is to provide an easy and efficient access to database information.
The database system was designed to manage a large amount of information. The management of data involves both the definition of the information storage structure and the provision of an operational mechanism for information. In addition, the database system must provide security assurance of the information stored.
Information is important in most organizations, and although user interfaces typically hide the details of the database behind them, the database is also widely used across industries. As a result, computer scientists have developed a large number of concepts and techniques for effective data management. These concepts and techniques are the subject of this book. In this chapter, we will briefly describe the rationale of the database system.
Objectives of the database system
Before the database system was created, and when some database systems were less complex, people used computers. Document processing system To store and manage data, generally using tree-shaped classification structures and documents in classification structures.
Possible problems in handling large-scale data using a document processing system
- Data redundancy and inconsistencies: Because of the different creators, the same information may be stored in multiple different files in different locations at the same time, resulting in waste of storage space and inconvenience of modification
- Data access difficulties: In the file processing system, the selection of data according to some pre-designed rule requires a data-processing component manually designed to be complex and difficult to achieve quickly
- Data isolation: difficulties of retrieval due to data redundancy and fragmentation
- Integrity issues: Data fragmentation makes it difficult to verify their completeness and rules
- Atomic question: Part of the operation (especially the modification of the data) needs to be completed at the same time or not at the same time, which is atomic, which is difficult for the document processing system to support
- Coincidence abnormal.: The design of the document processing system does not take into account the issue of co-production
- Authority Management: Users should see only what they are authorized to do, and decentralized data is difficult to manage.
The goal of the database system is to solve these existing problems.
Data View
Layered database design
Good data systems need to be able to address the issues that we have raised before, the most important of which is to simplify the interaction between the two and leave complex content to specialized maintenance staff through multiple levels of abstraction, without the need for end-users to have access to complex computer systems.
Normally, we need layers of architecture.
- Physical layers: The way in which data are stored on computer systems, the database relationship system will store data on computer systems in accordance with some preset rules. This is the subject of the development and maintenance of the database.
- Logical layer: higher than the physical layer, describing what data is stored in the data and how they are stored. Logic-level users focus only on the logic between their own data, and it is not their job to introduce it into the physical layer. This is where the database system administrator and related staff work.
- View layer: only one part of the database is described, the logical layer contains a large amount of data, users do not need to use them at the same time, and the view layer extracts data from the logical layer and presents it in a preset way, from which users interact with the database
Data Model
The basic structure of the data model database is the collection of conceptual tools describing data, data linkages, data syntax and data binding.
Data models directly guide how we design the logical layers, indirectly affect the design of our physical layers, directly affect the interactive methods of our database management systems and the design of the view layers.
Here are some of the usual data models.
- Relationship model : The relationship model uses the aggregation of tables to indicate the link between data and data. The database using the relationship model consists of a large number of tables, each containing a particular type of record. Each table consists of a large number of columns that store the data we need, and the use of departmental breakdowns allows us to link multiple tables into a whole.
- Entity-contact model (entity-relationship model): Entity-link model based on an understanding of the real world is an important part of the design of the database
- Object-based model (object-based data model): object-oriented program design has been described as the mainstream of software development, and object-based models are the product of ER models that add cover and method to integrate object-oriented thinking and relationship data models
- Semi-structured data model (semistructued data model): Semi-structured models are also inheritors of relationship models, but we allow the use of semi-structured data, of which XML is a typical example
We focused on SQL language in relationship models in the following studies, and studied E-R models for a complete relationship database from the beginning. XML, which is widely available on the modern Internet, is also studied after conditions have been met.
Database design
The high-level data model provides a conceptual framework for database designers to describe the data needs of database users and how the database structure will be structured to meet those needs. So,The initial phase of database design is a comprehensive picture of the data needs of the intended database usersI'm sorry. To accomplish this task, database designers need to communicate widely with experts in the field and users of the database.
Next, the designer selects a data model and uses the concept of the selected data model to convert those needs into a conceptual model for a database.
From the point of view of the relationship model, the conceptual design phase involves determining which attributes should be included in the database and how they should be organized into multiple tables. The former is essentially business decision-making, and we do not discuss it further in this book. The latter is primarily a computer science issue, which is addressed in two ways:
- One is the use of the entity-link model.
- The other is the attractive algorithm (commonly known as regularization), which treats all properties as losers. Generate a set of relationship tables
Finally, we need to structure well-designed relationship models at the logical level and to build the physical layers of their response, a process in which we can ask the database management system to have some of the characteristics we want.
Entity-link model
E-R data model used as a group calledEntitiesAnd the basic objects, and the ones that are between them.ContactI'm sorry. Entities are a “matter” or an “object” in the real world that can be distinguished from other objects. For example, each individual is an entity, and each bank account is also an entity.
DatabaseEntity describes by grouping of attributes (attribute)I'm sorry. They also form the attributes of the clusters of entities. In many cases, we use additional attribute ID to mark only (because both entities may have the same properties, so they need to be marked).
Contact It is the connection between several entities. For example, the contact links a teacher to her location. The sum of all entities of the same type is called the collection of entities (entity set), and the sum of associated entities of the same type is called the set of contacts (relationshipship set).
The overall logic of the database can be illustrated by ER maps, most commonly by the following:
- Entity grouping is expressed in matrix and contains the entity ' s name and the properties it owns
- Contacts indicate that the contact is inside the diamond.

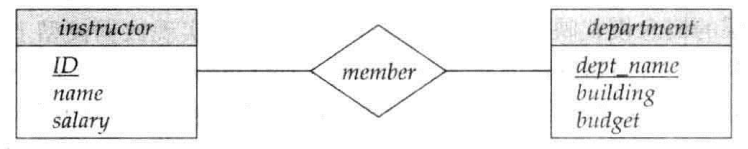
Normative
Another method used in designing the relationship database is what is often called a process of standardization. Its goal is to generate a relationship model that allows us to store information without unnecessary redundancy while at the same time having easy access to data.
This approach is to design a model that is appropriate to the appropriate paradigm, and to determine whether a relationship model is in line with the desired paradigm, we need additional information on institutions in the real world that model the database. The most common method is to use function dependency (funactional dependency)
We typically use a standardized test to test the database that we use ER models to see if it's reasonable to communicate and attribute, to duplicate information and to lose the ability to express a certain information.
Database system structure
The architecture of the database system depends to a large extent on the computer system operated by the database system. The database system could be centralized, client-server-type (one server is on mission for multiple client machines); it could also be designed for parallel computer system structures; and distributed databases would include multiple computers that are geographically separated.
Most users of today ' s database system are not directly connected to the database system, but are connected to it through the network. So we can distinguish between remote database users.Client and running database systemsServers (server)I'm sorry. Of course, when we use the database initially, we often put servers and client machines on a computer.
Users and administrators of databases
Normally, we divide the database users into four categories.
- Unexperienced users at all: they interact with prewritten applications, fill out forms according to the rules, and then pass the data back to the database for storage. They can also use the application to extract data from the database to the extent permitted by the rules.
- Application developer: Developers responsible for the development of computer applications, assisted by various development tools, to design rules for accessing databases to develop applications
- Skilled users• Access to databases using database search languages and data analysis software, which are not intended to develop applications but simply to access and analyse data
- Database Administrator: creation of databases, management of access rights to databases, daily maintenance of data Library
Introduction to the relationship database
Institutions in relation to the database
The relationship database consists of a collection of tables (tables) each with a unique name.A line in the table represents a link between a set of values, usually linking other information from a specific ID (non-duplicate). One table is the combination of these connections. Each column of the table represents the combination of attributes, i.e., the same type of information.
In the relationship model, relationships are generally used to indicate a table, and metagroups (tuble) to indicate a row in the table, and attributes (attribute) to indicate a column in the table. The relationship example (relationship example) indicates a particular line.
Relationships are the collection of the array of blocks, the order of which is not important for the database itself, and we are accustomed to ranking those groups in the order of the first attribute, and to view them separately when other orders are needed.
For each attribute of a relationship, there is a value-taking pool, i.e. the domain. This is taken into account when designing databases. We generally require that the domain be atoms, that is, irretrievable, so that we can just judge some issues by comparison with the value extraction and avoid designing other rules to extract data from the domain.
We allow the existence of empty values in the general database, which are currently unknown or non-existent, and in principle we will not leave him empty for the most important column in each table that is used as an ID.
Key
As we have said before, in order to distinguish between different groups of elements in a relationship, we need to achieve this distinction by an attribute (collective) called code. None of the relationships takes the same value on the key for two groups.
Superkey is a collection of attributes that can allow us to be the only one to determine a dimension in a relationship. We are generally only interested in those truths that are not supercodes, which are called candidate codes. Candidates are not unique in many databases.
Because the candidate code may not be unique, we use the main code (primary key) to indicate the candidate selected by the designer of the database. The choice of the master code must be careful and select those essentially unchanged attributes. We customarily put the master code at the front of all properties.
A relationship may contain the main code of another relationship mode in attributes other than its master code, which we call the foreign key. The presence of a code can help us quickly link multiple tables in a database.
Relationship query language and relationship operation
Query language indicates the language in which the user requests information from the database, which can generally be divided into process and non-processed
- Process language requires us to give us the specific process of searching.
- The unprocessed language requires us to give the specific information we want. The actual reference language used will include both process and non-processual elements, which can be consultedSQL Foundation
All process relationship query languages provide a set of calculations that can be applied either in a single relationship or in a couple, and these are of a common nature. The result of the calculation is always a separate relationship So people can combine these common calculations and get the data they want.
The most common relationship is a relationship that is chosen from a single relationship to satisfy a particular term, such as salary. > 500, his calculation results are a new relationship, a subset of the original relationship.
Another common practice is to select a specific column, and the result of the return is a new relationship with only specific attributes.
We also helped us to integrate multiple tables by comparing some columns from multiple tables.
Since the relationship is essentially a collection of blocks, the combination of the transactional calculations that apply to the aggregation also apply to the relationship, which is a vertical, column-adjusted method of consolidation.
We can all introduce the relationship here. SQL Foundation It's real practice.
Service
The service consists of queries and/or updates, and what we do, which is called a whole SQL code, can be called a service.
When a SQL statement is executed, it starts invisiblely, and when the following SQL statements are executed, it ends.
- Committee work: Submit the current transaction, keep the update of the transaction permanently in the database and start a new transaction automatically after Commit
- Rollback work: Rollback the current transaction, cancel the update of the database in this transaction and restore it to the status that it had before the first sentence of the transaction
Keywords, work, and you can omit them.
In fact, if some SQL codes we write are going to be fed back to the server immediately, we can't test them. The purpose of the transaction is to enable us to make changes to the database after we have confirmed the correct code.
The service exists to ensure that statements that update the contents of the database are atomic and thus avoid being updated Wrong.
As for better service design, which is usually a database administrator and argon to focus on, we need only write and submit SQL statements in accordance with their pre-established rules as users of the database.
Database design
Overview of the design process
The construction of a database is a complex element, including the design of the database model, design of access restrictions, design of procedures for updating data and design of the database security model. We are here to focus on the design of the database model, which, as for other relevant elements, is only brief, but, after all, is less general.
Database design must be based on a clear understanding of the needs of the database users and the application of the database user exchange, complete mapping of the data needs of future database users, and selection of appropriate data models based on demand, transforming the needs into the conceptual model of the database, in which case the most common means is the ER model.
A major part of the design of the database is to decide how to express the various types of services in the design, which is what is calledEntity He needs to include all clearly identifiable individuals, such as teachers in university databases, students, faculty courses, etc. These diverse entities are interlinked in many ways.
When designing the entity and their connection, two important shortcomings should be avoided.
- Redundancy: bad design repeats information, the most obvious problem with redundant information is in updating data, and when an information is updated but not in a copy, the database will have contradictory content
- Incomplete: Bad design prevents modelling in some places, and if only the opening of a course is not the storage of a course, the opening will repeat the entire information of the course, and the course that is not being held will not be able to be stored.
In the entity-link model, we try to solve the problems mentioned earlier, but when the database becomes large, it is not enough to rely on people to judge whether problems have occurred, so we will introduce some algorithms.
Entity-link model
The Entity Linking Model (E-R model) is the most common tool for designing databases, allowing for the mapping of the meaning of the real world and its interaction into conceptual models, most of which use the ER model concept. He uses three basic concepts, the set of entities and the set of contacts, the attributes. The ER model is also linked to ER. We'll introduce it separately later.
Entity Set
Entities refer to a subject and a matter in the real world, such as a student, a part of it. An entity has some characteristics, some of which can only indicate a group.
The Entity Cluster is a collection of entities of the same type (of the same nature), for example, the entire student body is an entity, and the entire teacher is also a teacher.
The clusters need not be intermingled, and one entity can be a multiplicity of entities at the same time, but in order to avoid redundancy, they may best contain different attributes.
The entity expresses, through a set of attributes, the descriptive nature of each member of the entity. Each attribute has a value.
Contact Set
Linkages are the linkages between entities, for example, between the teacher and the student entities, which are the mentorships. Linkages can be between entities in the cluster of entities or between entities in the same cluster of entities
The set of contacts is a collection of the same type of linkages, which forms a collection of a particular type of linkage in a separate abstract. The entity ' s function in connection is a role, and it needs to be known when it needs to be explained.
Links can also have descriptive attributes, such as mentorship, which can be described at a time when guidance begins.
The only contact examples of the focal points are used by the entities in which they are involved, so the descriptive attributes of our contact set are used for supplementary information, not for the contact set only
The contact set can be multi-dimensional, i.e., connect three or more entities, but the two-dollars are the most important.
When designing names of attributes of centralized connection, care is taken to avoid duplication, as they are mostly obtained centrally from other entities and can easily be duplicated in themselves, such as the most commonly used ID
Properties
Each attribute has a value-taking set called the property domain (domain). Each entity set can be marked with a set of (e.g. properties, data values) and each attribute corresponds to one of these pairs.
The properties of the ER model can be divided according to the properties type below.
- Simple properties and compound properties: Simple properties mean that he cannot be divided into smaller parts, and composite properties can, and the properties we use are currently simple, but we can also design composite properties in some modes, bringing together some associated properties, such as those of Adress, which contain the four simple attributes of STATE state code as their sub-resistence.
- Single and multivalue properties: this means that a property can be associated with a group of values instead of a value, and the properties we use are mainly single values
- Derivative properties: values of such properties can be obtained from other relevant attributes or entity derivatives (calculation), e.g. sum in the salary scale
Constraints
ER charts define the constraints that data in some databases must meet. Here's the introduction.
Map base
Map base figure (maping infrastructure) indicates the number of entities that an entity is associated with through a link to a cluster.
We'll meet at the binary.$R$ Collection of Contact Entities $A~ B$ At the time, the map base figure had four scenarios.
- One on one.
- - A pair of many.
- One more.
- Multiple pairs.
The map base of the special link set depends on the reality of the world that the link set out.
Participation constraints
If$E$Each of the entities involved in the communication Set$R$ In at least one of the links, E is described as all in R and the reverse is described as partial. We can limit all or part of the connection.
Key
The mechanism for the concentration of the entity is already described in the previous relationship model, where we can identify one entity only by using the master code, but how the linkage is marked is a problem.
We can be clear: The main number of the contact set depends on the number of the entity group to which it relates (the collection of attributes)
If the concentration of contacts does not have its own separate attributes, the only link can be identified using the master code of each entity to which it relates.
If the set has its own separate attributes, then a link needs to be determined using these master codes and their attributes.
Remove redundancy properties from entity concentrations
When we design databases using ER models, we usually start with the collection of entities that we contain, and the properties that are included depend on the designer's interaction with the user.
When the attributes of the different entities are selected and their counterpart is selected, the clusters of different entities are naturally established, and these links may lead to a concentration of the properties of the different entities that are redundant and need to be deleted. Let's use the following example.
Study Entity Sets
- Entity collection contains ID, name, dect name, salary where ID is the master code
- Entity collection contains dept name, writing, but where dept name is the main code
We link the two to the faculty of each teacher, and we can see that the attribute is present in both entities and that the property belongs to the master code, and should therefore be deleted from the instructor when the access is required by contact set inst dept
Extending the idea here to a database containing multiple entity sets and multiple contact sets allows the redundant properties to be removed.
Entity - Contact Chart
One entity - linkage chart with the main components below
- rectangles represent the entity set in two parts, containing the entity set name, attributes, where the primary key is underlined
- The diamond shape represents a set of contacts.
- Properties of undivided representative contact set
- Properties of physical and non-existent links to entities, and to contacts
If there's a problem with one-on-one, one-on-one, we use arrows on the real line to mark it from$A$Point$B$ This means that only one pair of these can be found.
If a compound attribute appears, the indented attribute should be used to indicate it.
In principle, the ER chart that we have produced should be a whole, with a whole picture of the entities, the links and the attributes.
Relationship design and good relationship design
We can create a relationship model of a relationship database directly from ER, and we want him to meet the appropriate paradigm (normal form), to make it easy for us to access information and not to be redundant. But the relationship model that is generated directly from the ER map may not be sufficient, and we need to discuss it further here.
We need to start with examples of the issues we're discussing.
Larger Mode
We're still discussing whether we can synthesize them into a collection of entities that contains all the attributes of both, so that we can reduce the multiple database connections that many queries need to use.
Unfortunately, we can find data redundancy problems, with each instructor having a bug, and each developing one, the same, which obviously leads to a risk of inconsistency.
We solved the problem of redundancy, and another problem was to establish a new relationship with an instructor because ID was the primary key, so we couldn't just build a new one, but we had to find a new teacher to build him.
Smaller mode
How do we find out that he's stored information in two different modes?
Of course we can rely on manual observation, but that's not very good. The big database is so huge that people have no energy to look for duplication.
We therefore need to study the normative approach that will be presented later and find the right decomposition. The division is not wrong, and it leads to the failure to effectively express the information that is already there.
That means we have two points of dissociation.
- Go to the redundancy caused by the original error of the merger.
- Avoiding the loss of new decomposition resulting in information
There are more common algorithms for decomposition.
- BCNF
- 3NF
Atomic Fields and First Parameter
The ER model allows for some degree of substructure of the entity set and the contact set, such as multivalue and group properties. But when we create tables from the ER model, we're going to eliminate this substructure.
- For group properties, each sub-relationship is called an attribute itself
- Creates a dollar for each item in a multivalue set for a multivalue attribute Group
In relationship models, we will not have any substructures of thought formalizing. A domain is atom, and the elements of that domain are considered inseparable units. We call the satisfaction of the atomic domain relationship pattern the first paradigm.
It is worth noting that we may have non-atomic domains in actual databases, such as ID for CS001, where CS is marked computer systems. That's what anyone who uses a database thinks, but as long as the database itself considers it indivisible, it's a first-class paradigm.
In practical use, users consider that the pattern is not satisfied, which is generally the compromise made by the designer for database performance or for ease of writing or proximity to reality for some queries.
It also means that sometimes we cannot solve problems in the database system and need to rely on more liberal programming languages to achieve the results we want. As to how to connect other languages and databases, we will discuss them when we look at the design of the program.
- Title: Database Systems Concepts: Data Models, Transactions, and Query Processing
- Author: Hyacehila
- Created at : 2024-12-23 11:42:58
- Link: https://hyacehila.github.io//blog/2024/12/23/database-systems-concepts/
- License: This work is licensed under CC BY-NC-SA 4.0.